Dlaczego żadne sortowanie nie pobije n log n
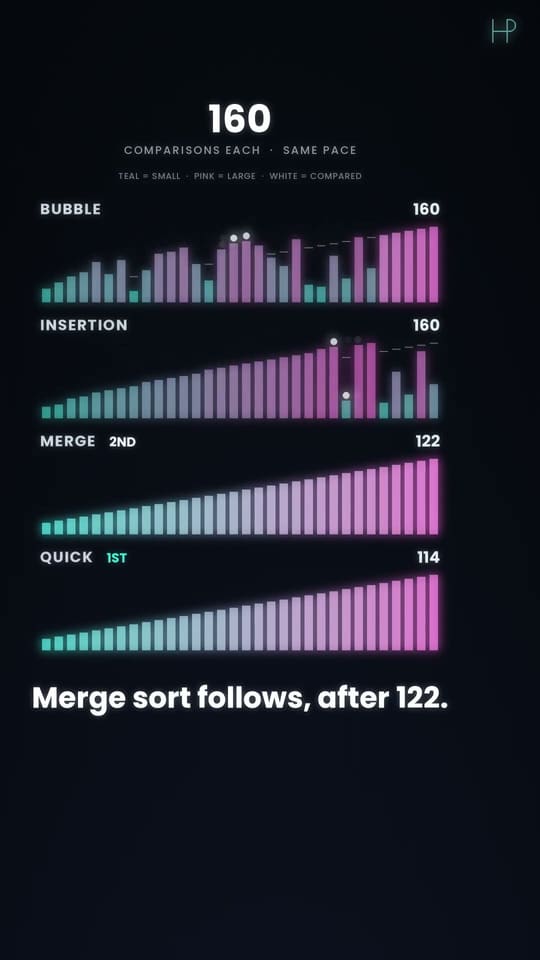
Różne algorytmy sortują te same potasowane dane. Każdy na swój sposób robi porządek z chaosu.
Film gra z YouTube po kliknięciu.
Dlaczego to działa
Potasuj talię i posortuj ją, porównując po dwie karty naraz. Jedne metody w kółko porównują sąsiadów; inne dzielą talię na połowy, potem na połowy połówek. Przy tym samym tasowaniu te drugie kończą dużo wcześniej i żadna metoda, która tylko porównuje, nie zrobi tego wiele lepiej.
porównania ≥ log₂(n!) ≈ n·log₂ n − 1,44·nsortowanie bąbelkowe: do n·(n − 1) ÷ 2
Zbuduj to w Pythonie
Python 3 · numpy · matplotlibCztery sortowania na tej samej potasowanej liście, z licznikiem porównań.
"""Sorting race: four algorithms on the same shuffled list, counting their comparisons.
Run: python sorting-race.py   (needs: pip install numpy matplotlib)
"""
import math

import numpy as np
import matplotlib.pyplot as plt

plt.style.use("dark_background")

n = 100
data = list(np.random.default_rng().permutation(n))
count = {"comparisons": 0}


def less(a, b):  # every algorithm compares only through this, so we can count
    count["comparisons"] += 1
    return a < b


def bubble(xs):
    xs = xs[:]
    for end in range(len(xs) - 1, 0, -1):
        for i in range(end):
            if less(xs[i + 1], xs[i]):
                xs[i], xs[i + 1] = xs[i + 1], xs[i]
    return xs


def insertion(xs):
    xs = xs[:]
    for i in range(1, len(xs)):
        j = i
        while j > 0 and less(xs[j], xs[j - 1]):
            xs[j], xs[j - 1] = xs[j - 1], xs[j]
            j -= 1
    return xs


def merge(xs):
    if len(xs) < 2:
        return xs
    left, right = merge(xs[: len(xs) // 2]), merge(xs[len(xs) // 2 :])
    out = []
    while left and right:
        out.append(left.pop(0) if not less(right[0], left[0]) else right.pop(0))
    return out + left + right


def quick(xs):
    if len(xs) < 2:
        return xs
    pivot, rest = xs[0], xs[1:]
    smaller = [x for x in rest if less(x, pivot)]
    return quick(smaller) + [pivot] + quick([x for x in rest if x not in smaller])


results = {}
for name, sort in [("bubble", bubble), ("insertion", insertion), ("merge", merge), ("quick", quick)]:
    count["comparisons"] = 0
    assert sort(data) == sorted(data)
    results[name] = count["comparisons"]
print(results, "| at least log2(n!) =", math.ceil(math.log2(math.factorial(n))))

plt.figure(figsize=(7, 4))
plt.bar(list(results), list(results.values()), color=["#f0abfc", "#c4b5fd", "#5eead4", "#5eead4"])
plt.axhline(math.log2(math.factorial(n)), color="white", linestyle="--", label="log2(n!): no comparison sort does better")
plt.ylabel(f"comparisons for n = {n}")
plt.legend()
plt.show()

# Try: n = 1000 (bubble sort needs about n*n/2, merge sort about n*log2(n))
Spróbuj: Ustaw n = 1000: licznik sortowania bąbelkowego rośnie około stukrotnie, a przez scalanie około szesnastokrotnie.
Poznaj ten skrypt linijka po linijce, z zadaniami i quizem → · uruchom go w Google Colab (po angielsku) →